The expanding scale of modern data volumes makes it increasingly difficult for human administrators to spot subtle anomalies across complex organizational networks. This challenge is compounded by the “insider threat,” a phenomenon where individuals with authorized access compromise network security through malicious intent or simple negligence. Traditional defense mechanisms, which often rely on static, signature-based detection, are failing to keep pace because they are designed to look for known footprints of external malware rather than the idiosyncratic deviations of a trusted user. To bridge this gap, a groundbreaking framework has emerged that integrates high-performance machine learning directly into the Linux Filesystem in Userspace (FUSE). By shifting the defensive perimeter to the storage layer, organizations can achieve continuous, real-time visibility that allows for immediate intervention against unauthorized activities before they escalate into full-scale data breaches. This approach moves security from the reactive realm of log analysis to a proactive stance within the filesystem itself.
Enhancing Security With Behavioral Analytics
Integrating Machine Learning and Linux FUSE
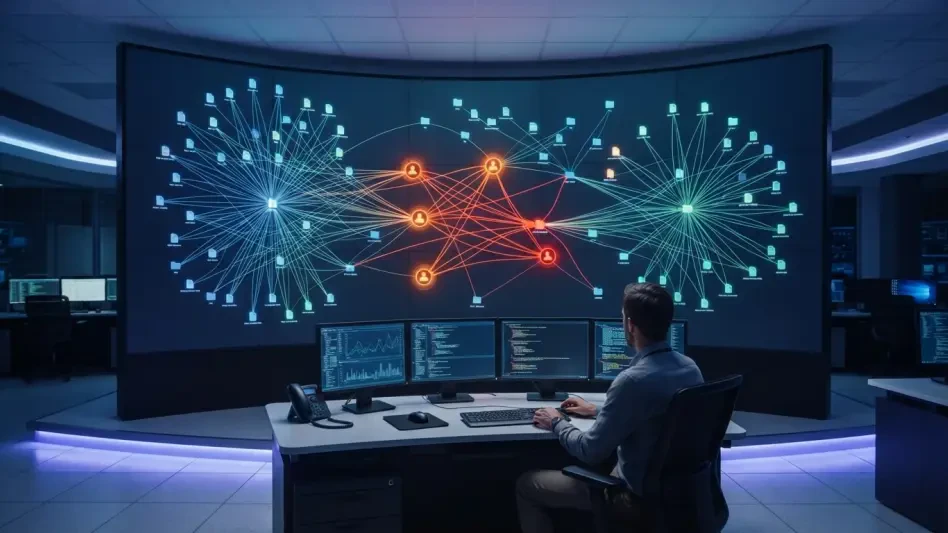
The core of this innovation lies in embedding adaptive user behavior analytics directly into the filesystem layer, creating a unified monitoring system that bypasses the limitations of traditional host-based security tools. By sitting strategically between user applications and the kernel, the system maintains a “bird’s-eye view” of all active file operations, which is essential for identifying patterns that might otherwise go unnoticed. This positioning ensures that the security engine can block or flag suspicious actions before they are fully executed, significantly reducing the risk of data exfiltration during high-stakes operations. Unlike older methods that waited for log files to be written and then parsed, this real-time interception allows for a defensive posture that acts at the speed of the hardware itself. The ability to inspect every read and write request as it travels through the stack provides a granularity of control that was previously only available through heavy kernel modifications.
Leveraging the Linux Filesystem in Userspace (FUSE) allows for the creation of virtual filesystems that operate without requiring deep kernel modifications, ensuring both high-speed performance and organizational system stability. This architectural choice is particularly beneficial for modern enterprises that require seamless integration with existing software stacks without the risk of system crashes associated with experimental kernel-level drivers. Furthermore, the use of FUSE allows the system to remain entirely transparent to the end-user, maintaining a fluid and uninterrupted experience while scaling efficiently alongside the rapidly expanding organizational data volumes of 2026. This transparency means that employees can continue their standard workflows without being hindered by intrusive security prompts, yet the organization retains the ability to monitor every interaction at a fundamental level. This move toward non-intrusive yet pervasive security protocols reflects a shift toward more resilient infrastructures.
Applying Isolation Forest for Anomaly Detection
To differentiate between routine work and malicious activity, the framework employs the Isolation Forest algorithm, a choice specifically suited for cybersecurity due to its efficiency in high-dimensional data spaces. This machine learning model is uniquely effective because it focuses on isolating “outliers”—those rare data points that deviate from the majority—instead of trying to define every possible iteration of “normal” behavior. In a corporate environment where user habits are diverse and unpredictable, attempting to whitelist every safe action is nearly impossible and often leads to administrative burnout. The Isolation Forest avoids this trap by assuming that anomalies are few and different, which allows it to identify threats with significantly less computational overhead than traditional clustering methods. This approach ensures that the detection engine can process thousands of filesystem events per second without introducing noticeable latency, making it a viable solution for large-scale enterprise data centers.
The detection process begins by establishing a rigorous behavioral baseline for each individual user, learning their typical access frequencies, peak activity hours, and standard data modification volumes. Once these norms are set, the engine evaluates every new action in real-time; if an activity deviates significantly from the established baseline, it is assigned a high deviation score for further investigation by security teams. This scoring system is dynamic rather than static, meaning that the algorithm continuously refines its understanding of what constitutes a deviation based on a sliding window of historical data. For instance, if a developer begins working on a new project that requires access to a different repository, the system can eventually incorporate this shift into its baseline, provided the change is gradual and follows logical patterns. This adaptive capability reduces the incidence of false alarms that typically plague static systems, allowing human administrators to focus on the most credible threats.
Utilizing Contextual Profiling and Automated Response
A sophisticated security model must understand not just what a user is doing, but also the specific context surrounding those actions to minimize false positives and maximize threat detection. This system utilizes temporal profiling to track the timing and frequency of file interactions, which serves as a powerful indicator of potential account compromise or insider maliciousness. For example, if an employee who typically works during standard business hours suddenly begins accessing a high volume of sensitive files at three o’clock in the morning, the temporal profiler will immediately flag the activity as a high-risk anomaly. This layer of analysis is particularly critical in 2026, where remote work and global teams mean that standard office hours are less defined, yet clear patterns of individual behavior still emerge. By tracking these temporal rhythms, the machine learning engine develops a nuanced understanding of each user’s professional life, making it much harder for an attacker to hide.
Simultaneously, spatial profiling monitors the scope and location of file interactions across the directory structure, identifying when a user accesses sensitive areas that are unrelated to their job function. This is especially useful for detecting lateral movement, a common tactic where an attacker or a disgruntled insider explores the network to find valuable assets after gaining initial access. By mapping the spatial footprint of a user’s typical workflow, the framework can recognize when a marketing professional suddenly starts probing financial records. Detected anomalies are then classified into a structured three-tier severity system—benign, suspicious, or critical—to ensure an appropriate and measured response level. Critical threats activate automated defensive measures such as revoking user access or blocking specific file requests the moment they occur, ensuring that threats are contained instantly in the seconds before data integrity is compromised.
Implementing Adaptive Defense for Future Growth
The shift toward intelligent storage represented a fundamental change in defensive strategy, moving away from perimeter-focused models to an internal, data-centric approach. Organizations that adopted these filesystem-level machine learning frameworks experienced a marked improvement in their ability to contain threats within the first few seconds of detection. This proactive stance was particularly effective in mitigating the risks associated with the rapid data expansion seen from 2026 into the following years. By making the filesystem itself the primary arbiter of user behavior, security teams gained a level of visibility that bypassed traditional network obfuscation techniques. The results from early implementations showed that a deep integration of machine learning at the storage layer was not merely a technical upgrade but a necessary evolution in maintaining data sovereignty.